AI News
Anthropic 详解 Opus 5.5 上一次 Claude Code 任务的成本构成
原文把一次任务的 token 成本拆成轮次、缓存、输出和模型选择四项,并给出 effort 设置与缓存维护的可迁移省钱方法。
Anthropic 官方博客拆解 Claude Code 任务在 Opus 5.5 上的成本构成,轮次、缓存读取、输出 token 和模型选择决定账单,Opus 5.5 API 输入输出每百万 token 降价 20%、缓存读取降 60% 至 $0.20。
你并不是一开始就打算购买数百万个 token。你是为了构建一个功能、完成一次迁移,或者运行一项任务。token 数量只是模型为达成目标所需要的量。
两个每 token 成本相同的模型,在同一项任务上的花费可能相差很大。一个只读一遍代码。另一个读了代码,尝试修复,然后又读一遍。其中每一步都是一轮,而每一轮都会重新发送到目前为止的对话。因此,需要更多轮的模型花费更高,即使单价相同也是如此。
读完这篇文章后,你应该能够回答关于自己工作的三个问题:
我想事先说明的权衡是:每一种减少 token 消耗的方式,也可能让你付出任务无法完成的代价。降低 effort、使用更小的模型,或者减少上下文,这些当然都能节省 token。但一次重试的成本会超过这些节省。本文试图为每一种权衡标出价格。
这里的一些数字是标价,另一些则是基于标价构建的示例。这些数字是可交互的,所以你可以在阅读时更改输入。这些都是尽力而为的示例,所以请务必查阅我们的文档,并自行核算。
Claude Code 中的一个任务就是一个循环。模型读取对话,调用工具,读取结果,然后再次循环,直到完成。循环中的每一轮就是一次请求。有四件事决定了这个循环的成本。
轮次。每一轮都会重新发送到目前为止的对话。轮次越少,处理的输入就越少。
缓存读取。一轮中重新发送的大部分内容都是模型在上一轮已经看过的文本。这部分按缓存读取计费,价格仅为输入价格的一小部分。
输出 token 类型。这是最贵的 token,价格是输入的五倍。思考按输出计费,因此一个在得出答案的过程中推理更少的模型,成本更低。
模型。每个模型都有自己的价格,列在定价页面上,因此你选择的模型决定了每一个 token 的价格。
我们的示例使用 Opus 5.5 的 API 标价:每百万输入 token 4 美元,每百万输出 token 20 美元,每百万缓存读取 0.20 美元。与下方的计算器一样,这些示例将缓存输入按读取价格计费,其他所有内容按输入价格计费,并且不计缓存写入。token 数量仅为示例说明。
假设一个任务开始时上下文为 20K tokens,随着模型读取文件和工具结果,增长到 120K。在第 40 轮时,平均每轮发送约 70K tokens。这个任务大约消耗 2.8M 输入 tokens,尽管对话从未超过 120K。如果 90% 从缓存读取,输入成本约为 $1.62。同样的任务在 25 轮内处理约 1.75M tokens,输入成本约为 $1.02。
一轮的成本高于它新增的 tokens,因为它会重新发送之前的所有内容。所以最便宜的一轮就是你不需要的那一轮。
一个能减少轮次的习惯是给模型一种检查自己工作的方式。例如,一个可运行的测试、一次构建,或一个调用该端点的脚本。能够检查自己工作的模型会更早发现自己的错误。
一个能在一次遍历中收集所需内容、并批量执行工具调用的模型,也能减少重新发送的次数。
同样的 2.8M 输入 tokens,如果没有任何来自缓存,成本为 $11.20。在 90% 命中率下成本为 $1.62,在 96% 时约为 $0.99。没有其他设置能如此大幅地影响输入成本。一个稳定的会话本身就能保持高命中率。我在本文后面会介绍一些避免破坏缓存的注意事项。
在 Opus 5.5 上,一个输出 token 的成本是一次缓存读取的 100 倍。一个典型任务的 60K 输出 token 花费 $1.20,与从缓存中读取 6M token 相同。输出包含思考过程。即使 Claude Code 只向你展示摘要,你也要为全部内容付费。这就是为什么 effort(主要改变模型思考量)会让账单变化如此之大。
缓存读取更便宜的模型主要有利于长会话。输出更便宜的模型主要有利于需要大量推理的任务。
有两处变化:价格,以及模型完成的工作量。
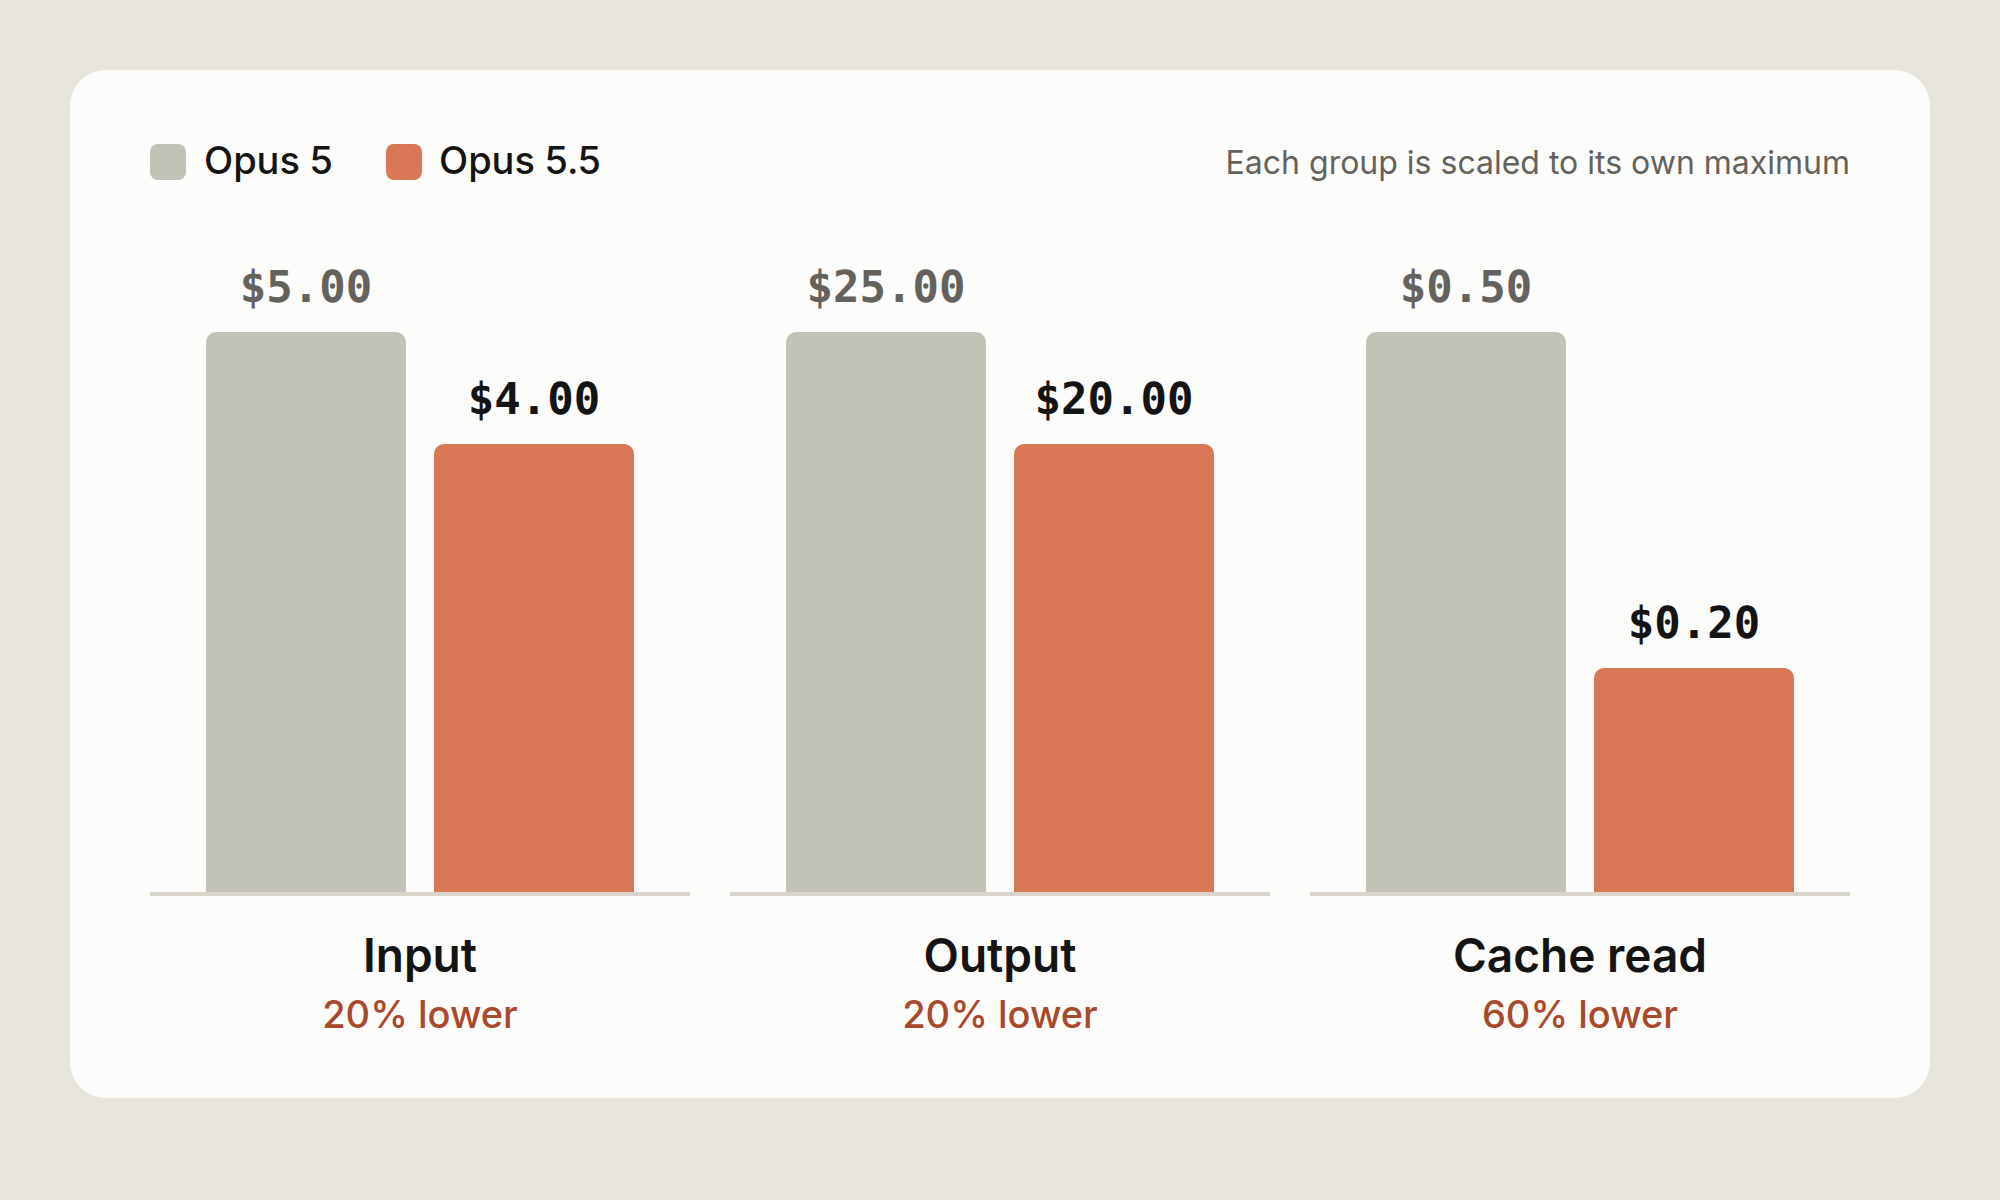
每一条价格线都更低了。输入和输出 token 比 Opus 5 便宜 20%。缓存读取便宜 60%。输入价格下降,读取费率也随之下降,从输入价格的十分之一降至二十分之一。图 A 比较了两个模型每百万 token 的价格。这些是 API 标价。在 Pro、Max 或 Team 套餐上,Opus 5.5 更低的价格会传递到你的限额上,包括缓存上下文,因此它们比 Opus 5 大约多出 25% 的可用量。缓存读取的额外降价属于 API 价格变动。
在使用 API key 的情况下,缓存读取降价对 Claude Code 影响最大。一个长时间运行的智能体会话将大部分输入花在缓存读取上。在下方图 B 所定价的会话中,缓存这一行从 $1.00 降至 $0.40,是账单上降幅最大的一项。
你能节省多少取决于你工作的形态。一个以缓存读取为主的会话,在输入上最多可节省 60%。一个没有缓存、答案很长的简短提问,最多可节省 20%,因为输出占了主导。大多数 Claude Code 任务介于两者之间。下面的计算器会显示你的任务处于哪个位置。
Opus 5.5 在一个回答上可以使用更多 token,因为它在回复前总会先思考。我们预计人们用 Opus 5.5 能完成更多工作,但这因任务而异,所以要在你自己的工作上测量。图 C 比较了两个模型上每个任务的成本。这一部分取决于你的工作,其影响远大于价格。
在一个范围明确的任务上,两个模型完成的轮数大致相同,降价就是你得到的全部好处。差距应该在开放式任务上最大,因为模型可能在一个错误的想法上耗费很多轮。没有哪个单一数字适用于所有代码库,所以要测量它(见最后一节)。
长时间运行以一份报告收尾。 Opus 5.5 会以它改动了什么、发现了什么以及需要你提供什么来结束一次长时间运行。这也能省钱,因为当你能看到发生了什么时,你重跑会话的频率就会降低。
图 B 以相同的 token 数量为两个模型上的同一个会话定价。所以差异就是价格变化,别无其他。切换模型即可对比。token 数量仅为示意。
按 Opus 5 的标价
同一会话在两种模型上使用相同 token 的示例,因此这里仅体现价格变化。
图 B。同一会话在两种模型上使用相同 token 的示例,因此这里仅体现价格变化。
这张账单包含 /usage 为某次会话显示的三行。按 token 计,缓存读取是最大的一行,为 2M。按 token 计,输出是最小的一行,但按成本计却是最大的一行。全新输入介于两者之间。它涵盖每个文件的首次读取以及每个新的工具结果。
图 B 给两种模型相同的 token 数量,因此它仅体现价格变化。你自己的会话在 Opus 5.5 上可能使用更多或更少的 token。按这种方式计价,该会话的成本大约低 31%。
一次实际记录的运行还会叠加第二个效应,即模型完成工作量的变化。在一个出现起步失误的任务上,差距应该会拉大。试试你自己的数字
设定你某个任务的使用量,或者从预设值开始。这些预设值颇具示例性,但我仍然建议你自己算一算。缓存输入按缓存读取价格计费,全新输入按输入价格计费,因此缓存滑块展示了差距中有多少来自缓存读取。
要用真实会话填充这些滑块,请在任务结束时运行 /usage。Session 区块会给出输入、输出和缓存的数据。最后一个滑块是你对 Opus 5.5 在你的任务上能少做多少工作的假设。如果只想看价格变化,就把它留在 0%。
要根据你自己的实际工作来设定它,方法如下:在 Opus 5 和 Opus 5.5 上运行同一个任务,比较轮次和输出 token。Measure it yourself 会带你走一遍流程,Reading a session 则展示了在 /usage 中该检查什么。
所有轮次中发送给模型的内容,无论是否命中缓存。
包含思考内容,它按输出计费。
只看价格就留在 0%。Opus 5.5 用更少的 token 做更多的事,但这要在你自己的任务上实测。
Opus 5 每任务
Opus 5.5 每任务
一个月按工作日计算。采用标价。不含批量或批量折扣,且不计入缓存写入(见下方缓存部分)。
Opus 5.5 更低的价格让每个 token 的成本更少。你如何运行会话决定了你使用多少 token,以下步骤会有所帮助。
Effort 为模型每一轮消耗多少 token 设定了一个总体倾向:包括它的思考、它写出的文本以及它的工具调用。在较低的 effort 下,它进行的工具调用更少,且调用更简短。Opus 5.5 有四个级别(low、medium、high 和 xhigh),外加用于单次会话的 max。在下方选择一个级别,查看何时使用它以及设置它的命令。
级别从每轮最少思考到最多思考依次排列。
Claude Code 会为每个模型设定一个默认级别,`/effort status` 会显示你的当前级别。对于范围明确、日常性的工作,可以试试 medium。当 medium 卡住时,试试 high。它每轮的开销比 medium 更高,但低于换用更大的模型。对于机械性的工作,比如重命名或在多个文件中应用已知模式,使用 low。
一个粗略理解 effort 定价的方式:假设 high 在一个任务中额外增加 20K 思考 token。在 Opus 5.5 上,这就是 $0.40。一个十轮的 retry 循环,使用 100K 缓存上下文,总共 10K 输出 token,成本大致相同。所以,如果 high 能在一个任务中省下一次 retry,它就值回成本。而在一个 medium 本可以一次就完成的任务上,它就是浪费。
你需要更高 effort 的最明显信号,是修复只停留在一层。
假设某个字段在 API 处理程序中被重命名。在 medium 档位下,模型更新了处理程序,处理程序的测试通过了,但客户端仍然发送旧字段。它做了被要求做的事,只是没有读得足够远,去找到第二个调用方。在 high 档位下,它会在写入之前花更多轮次阅读调用点,并一次性修改两层。
检查也能捕获同样的 bug。如果模型能运行一个经过客户端的测试,那么在 medium 档位下,旧字段在写入的那一轮就会让该测试失败。所以在你提高 effort 之前,先检查模型是否有办法验证自己的工作。运行一次测试的成本是一轮加上其输出。而更高的 effort 会给每一轮都增加思考。
如果升级 effort 档位和增加检查都不奏效,那就换用更大的模型。
在 Claude Code 中,运行 /effort 并带上档位,例如 /effort high。/effort status 会打印当前档位。你可以在任务进行中更改它,新档位会应用于下一个请求。
更改 effort 或 thinking 设置会清除缓存的对话,因为这些设置是缓存所匹配的提示词的一部分。下一个请求将按整段对话支付缓存写入的费用。
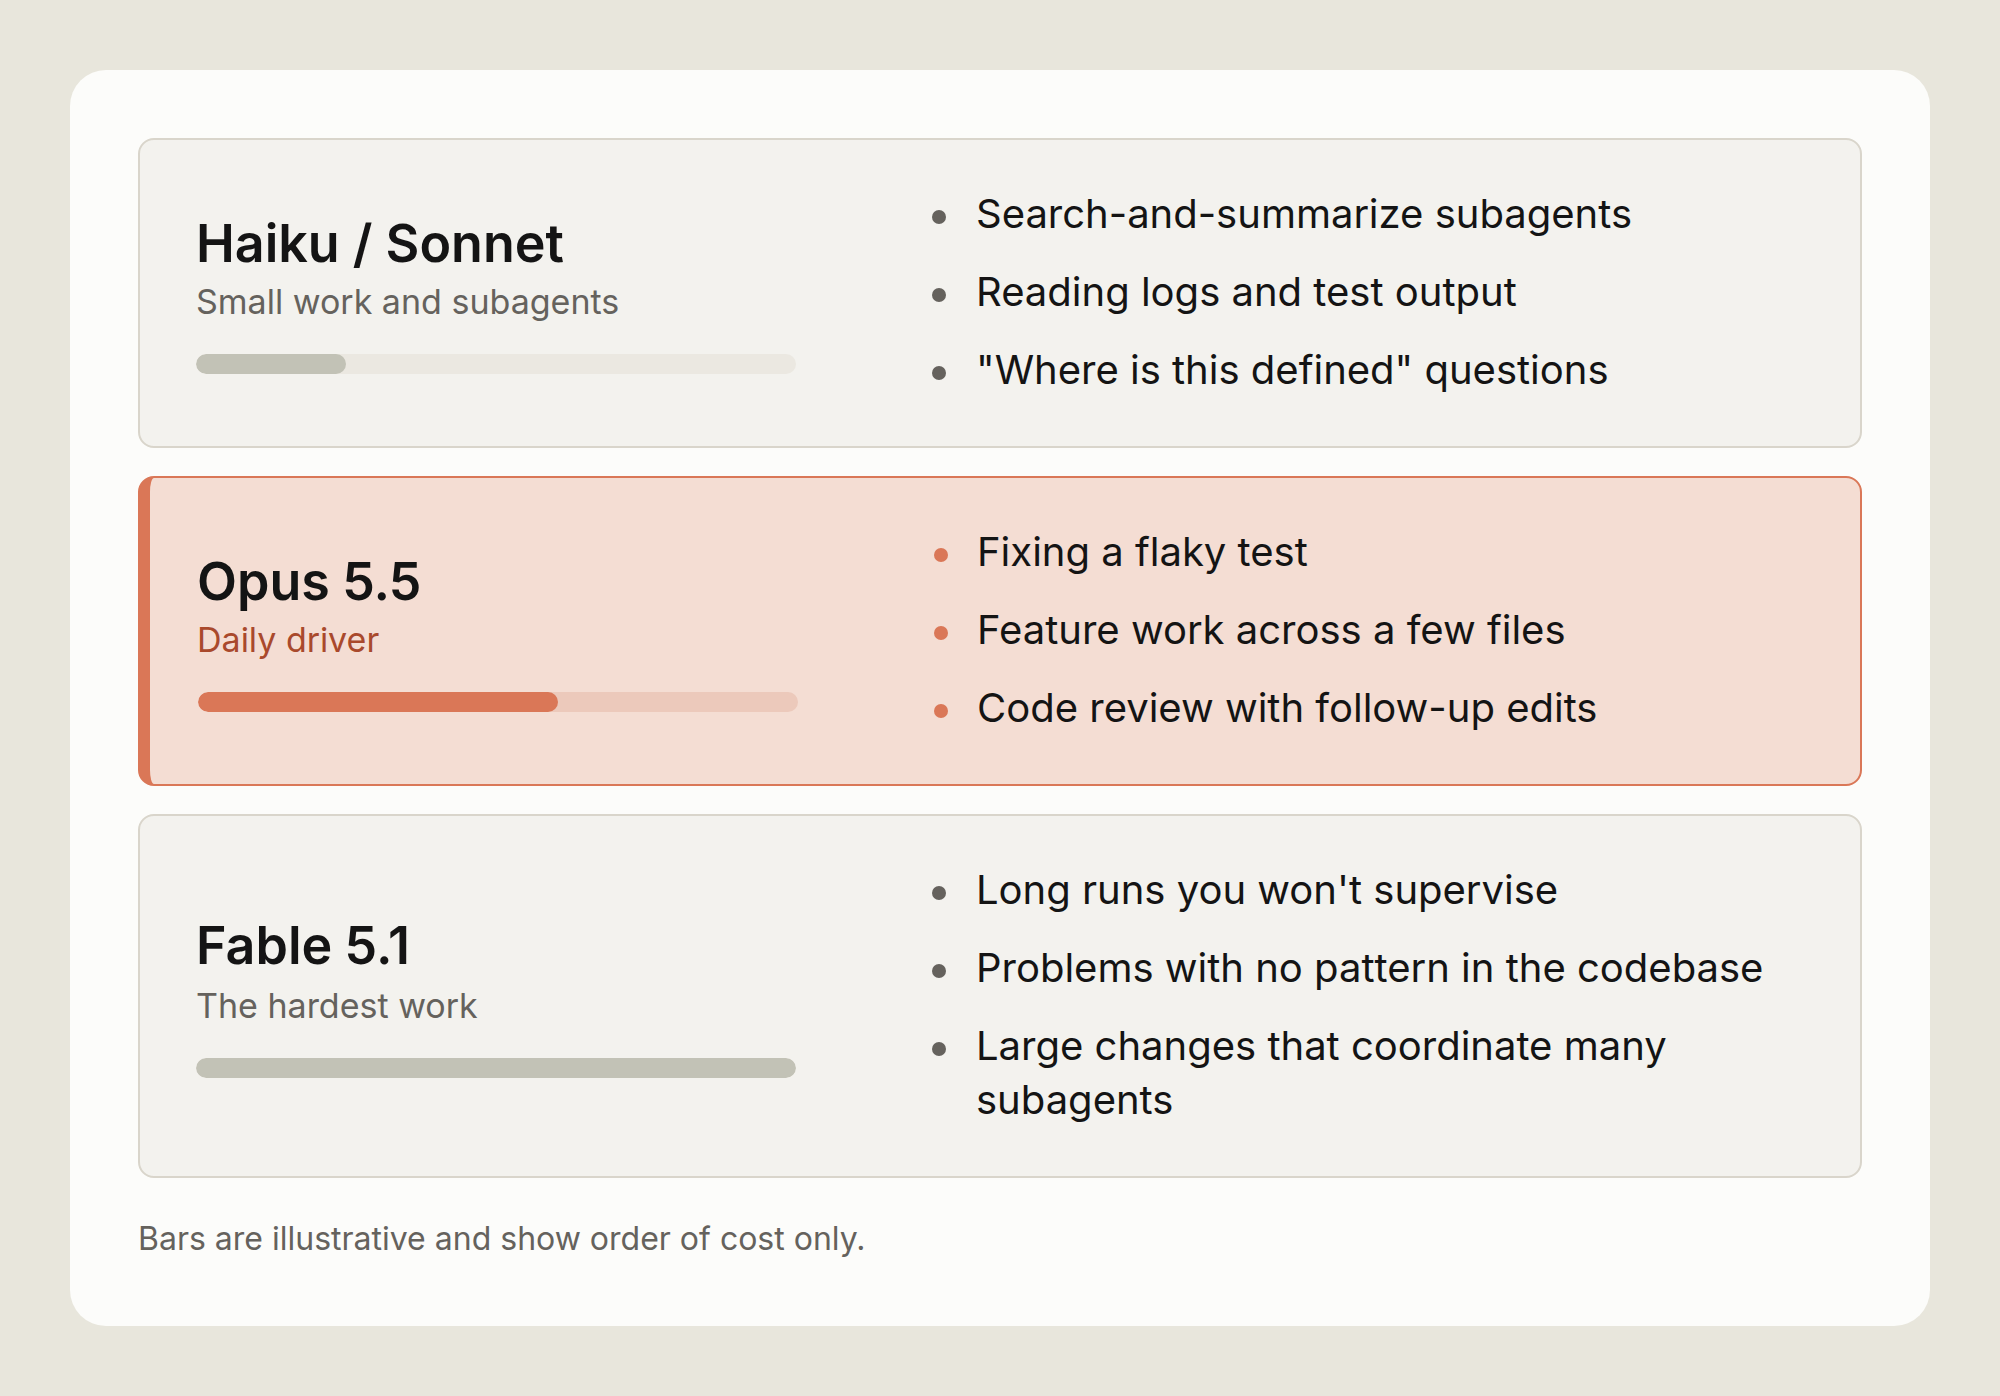
模型选择决定了一次会话中每个 token 的价格,因此它对账单的影响比 effort 更大。它的影响还更深远。每一个继承主模型的子智能体也会继承它的价格。大多数日子需要三种模型:一个用于查找的小模型、用于你密切监督的工作的 Opus 5.5,以及用于最难任务的更大模型。
将 Opus 5.5 用于你监督的工作:跨几个文件的功能开发、调试,以及带有后续修改的代码审查。你阅读它的操作,并在它偏离时介入,从而让循环保持简短。升级到 Fable 5.1
当结果比 token 价格更重要时,升级到 Fable 5.1。例如你不会监督的长时间运行、代码库中没有现成模式的问题,以及需要协调许多子智能体的大型改动。不要等到第三次失败。如果 Opus 5.5 在高强度下两次遇到同一个问题,就切换,等它解决后再切回来。对于交互式工作,Opus 5.5 更合适,因为它延迟更低、成本更少。
Fable 5.1 的标价是每百万输入 token 10 美元、每百万输出 token 50 美元,是 Opus 5.5 价格的 2.5 倍。其缓存读取费用为每百万 0.25 美元,仅为 Opus 5.5 费率的 1.25 倍,因为它们是按输入价格的 0.025 倍计费的。因此,在长时间、缓存密集的运行中差距最小,而在大量写入的任务中差距最大。
在自然的断点处切换。缓存属于上一个模型,因此在新模型上的第一轮会为整段对话支付写入成本。先运行 /compact,或者用一个简短的书面计划开启新会话,让那一轮更小。运行 /model 并带上别名或模型名称即可切换。/model 还会把你的选择保存为新会话的默认值,所以等困难的部分完成后就切换回去。
降级到 Sonnet 或 Haiku 用于查找,而不是用于写代码:用于搜索和总结、读取日志和测试输出,以及"这个定义在哪里"这类问题的子智能体。对于跨多个文件的机械式编辑,保留 Opus 5.5 并将 effort 设为 low。这样编辑仍由编写你其余代码的那个模型完成,而每轮成本更低。
要让某个子智能体使用更小的模型,在其定义中设置 model: haiku 或 model: sonnet。要让所有子智能体都使用同一个模型,设置 CLAUDE_CODE_SUBAGENT_MODEL 环境变量。子智能体定义中指定的模型会覆盖该变量。未设置模型的子智能体会运行在你的主模型上,除非该变量已设置。
每个子智能体都在自己的上下文窗口中运行,并返回一份摘要,因此它读取的文件不会进入你的主对话。它仍然要为自己的 token 付费,所以模型设置决定了这笔开销的多少。
权衡在于:一个会误读搜索结果的小模型,会把主模型引向错误的文件,而主模型要为这段弯路付出代价。让小模型去做那些出错后容易发现的工作,比如查找文件、运行测试和读取日志。
把需要判断的决策留给主模型。opusplan 别名以另一种方式拆分工作:Opus 在 plan 模式下做规划,Sonnet 执行该计划。这就把代码编辑交给了 Sonnet,与上面的建议正好相反。在把它设为默认之前,先在你自己的任务上实测一下。
为旧模型编写的指令会让 Opus 5.5 写更多内容并重复调用工具。在 Claude Code 中运行 /claude-api prompt-audit,检查你的 Claude Code 配置(例如你的技能和 CLAUDE.md 文件)是否存在这些提示词反模式。它还会检查你在 Claude Platform 上构建的应用的代码。
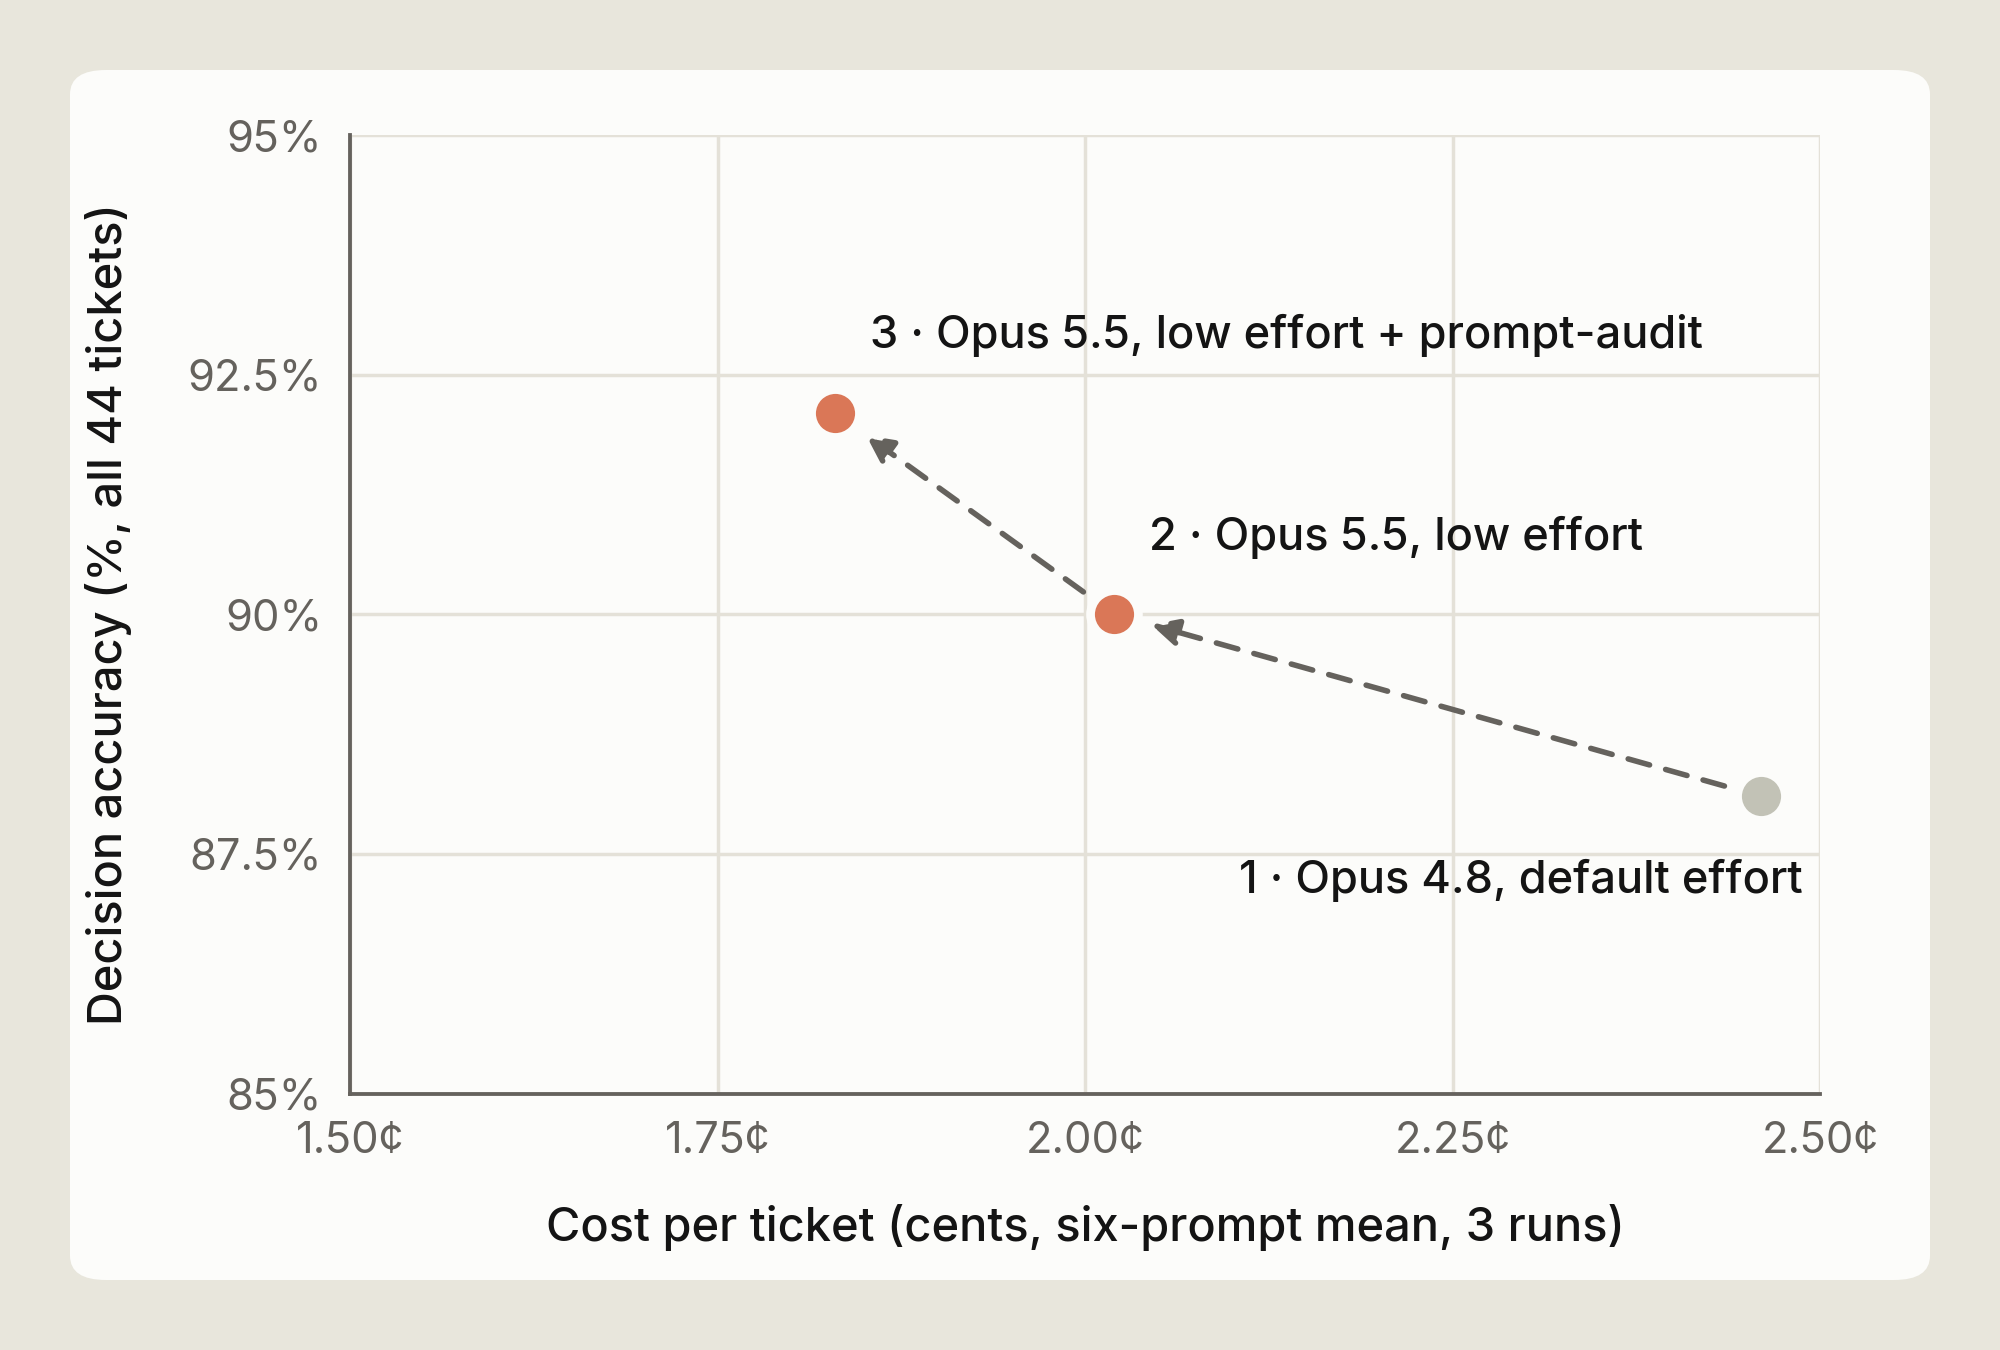
我们在一次从 Opus 4.8 到 Opus 5.5 的迁移中测试了这一点,使用了一个包含 44 张工单的内部客户支持基准,其提示词中包含若干这类模式。迁移到 Opus 5.5、采用低 effort 后,该基准的成本降低了约 18%。
运行 prompt-audit 又进一步降低了 9%,最终比 Opus 4.8 的起点低约 25%。这次审计移除了那些让模型写更多内容并重复调用工具的仪式性指令:一个强制性的六步流程、一条草稿纸规则、一条验证两次的规则,以及相互矛盾的指令。
这一结果来自单一基准测试,因此请将其视为一个示例,而非可以预期的数字。先运行审计,然后在真实任务上对比使用前后的 /usage(参见"自行测量")。
Claude Code 会为你处理缓存与压缩。你如何运行会话,决定了它们能节省多少。
Claude Code 会缓存请求中重复的部分,例如系统提示词、工具定义以及到目前为止的对话。
在 Opus 5.5 上,一次缓存读取的成本是全新输入 token 的 5%。写入缓存的成本高于全新读取,按当前定价,五分钟缓存为输入价格的 1.25 倍,一小时缓存为输入价格的两倍。每次命中都会免费重置生命周期。
在 Claude Code 中,生命周期取决于你的付费方式。使用 Claude 订阅时为 1 小时。使用 API key 或云服务商时默认是 5 分钟,而订阅一旦开始消耗用量额度,也会降为 5 分钟。
在 120K tokens 的上下文下,用 Opus 5.5 写一次五分钟的内容大约花费 $0.60,读一次大约 $0.02。一次写入的成本相当于 25 次读取。使用 API key 时,一次六分钟的咖啡休息会把下一次 $0.02 的读取变成 $0.60 的写入。同样规模下,一小时的写入大约花费 $0.96,而在 API 上,你可以支付这笔溢价来填补一天中的空档。
缓存存储的是一个前缀,因此它只能复用请求中从开头起与上一次请求相匹配的那部分。
一个稳定的会话每一轮都会在对话末尾追加内容,从而保持较高的命中率。任何改动请求中较早部分的操作都会降低命中率。更改工具定义会清空整个缓存,而更改系统提示词会从该点起清空缓存,这几乎就是全部内容了。
在实践中,以下情况预计会发生缓存写入:
因此,在会话启动时就把这些设置好,然后在它工作期间不要改动它们。
每一轮都会重新发送整个上下文,因此随着上下文增长,一轮的成本也会增加,即使缓存是热的也不例外。在 20K tokens 的上下文下,一轮的缓存读取在 Opus 5.5 上花费约 $0.004。在 150K 时花费约 $0.03,而在这个规模下进行 30 轮,仅读取就要花 $0.90。
同样的 30 轮在 20K 下花费约 $0.12。在 Claude 4.6 及之后的模型上,更大的上下文窗口不会改变每 token 的价格,因此成本完全来自重新发送对话。
这些上下文中有很大一部分是早先工作遗留下来的:一小时前的堆栈跟踪、你已经处理完的文件、你后来已经修复的测试运行输出。每一轮这些都仍会被发送。
当会话接近其上下文上限时,Claude Code 会总结较早的历史记录,以便后续轮次发送更少内容。运行 /autocompact 并带上一个 token 数量,可以更改在此发生之前上下文达到多满。
两条命令可以让你自己完成这件事。/clear 会清空对话且不产生任何费用,所以当你转向不相关的工作时就用它。/compact 会保留连续性,代价是一次请求。它会读取自己要总结的对话,你可以说明要保留什么,例如 /compact keep the failing test names and the schema change。
在 150K tokens 时进行压缩的大致价格约为 $0.25。这包括读取、几千个输出 token 的摘要,以及在更短上下文上的一次新的缓存写入。之后每一轮大约能节省 $0.025 的读取费用,所以这次压缩大约在十轮之内就能回本。在你即将结束时才做压缩,花费会超过它节省的。
摘要还会丢失细节。在调试过程中途做一次压缩,可能会丢掉那行唯一重要的日志。要在自然的停顿点压缩,而当下一步依赖某个具体内容时,就在 /compact 指令里说明。
你的 CLAUDE.md 文件会在每次会话开始时加载进上下文,所以其中的每一行都是每一轮都会重新发送的内容的一部分。成本文档建议将其保持在 200 行以内。MCP 工具定义是延迟加载的。开始时只加载工具名称和服务器指令,当某个工具被使用时才会加载它的完整定义。运行 /mcp 可以查看哪些服务器已连接,并关掉你没在用的那些。
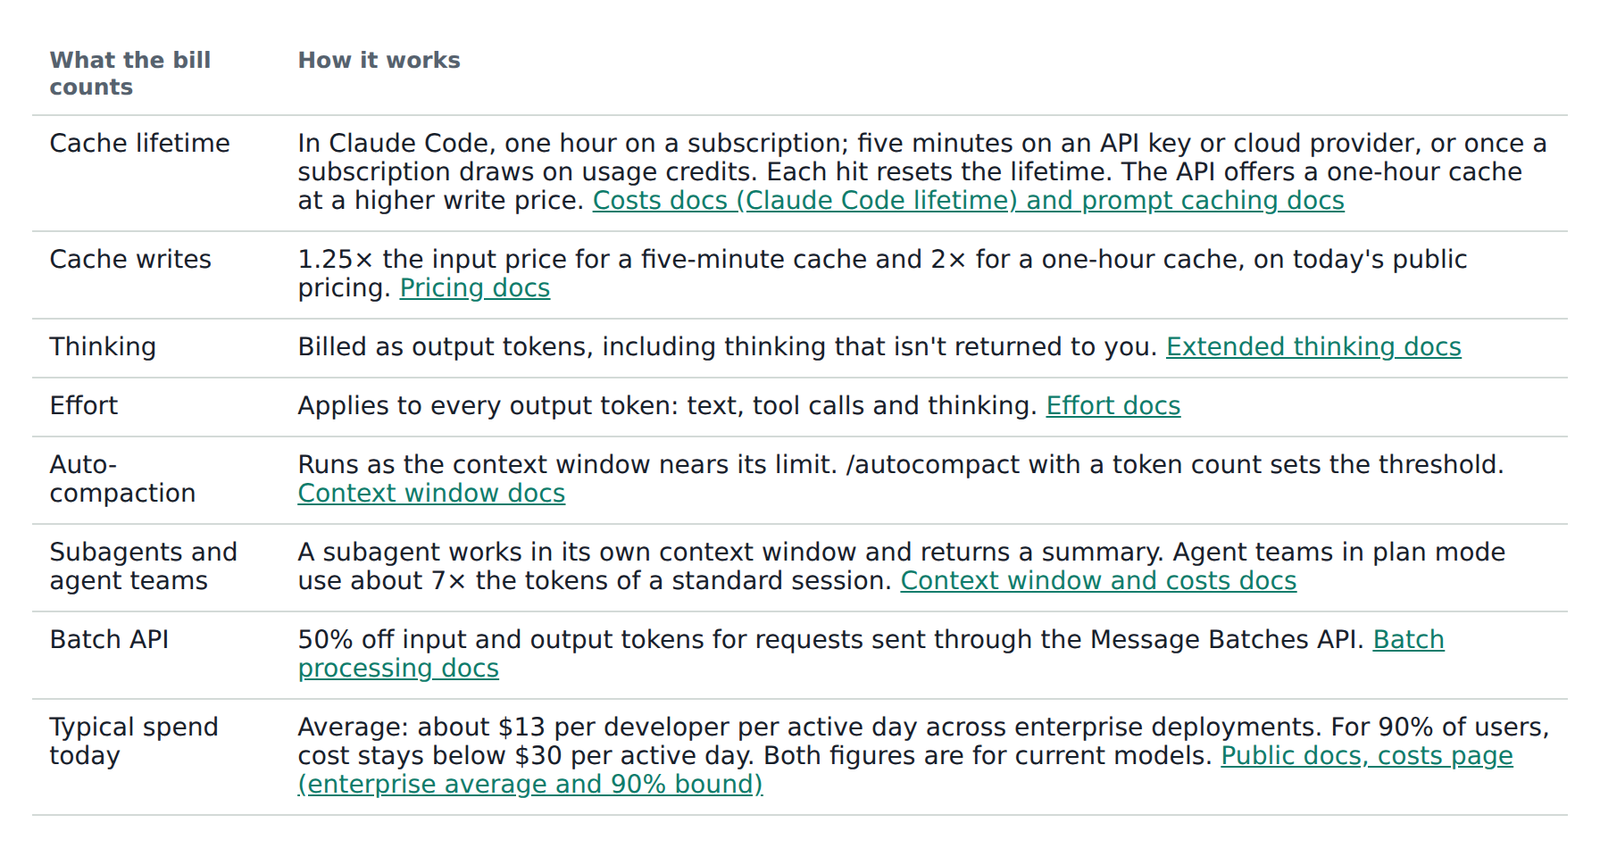
该表格列出了其他会影响 Claude Code 会话的计费规则,并在有文档可查时附上了相应链接。
本文中的数字仅为示例。你的代码库、提示词和习惯各不相同,因此请针对自己的任务测量成本。以下是检查方法。
在任务结束时,检查 /usage 中的三件事。
作为基准,Claude Code 成本文档给出的企业部署平均值约为每位开发者每个活跃日 $13,而 90% 的用户每个活跃日低于 $30。如果一次会话的成本远高于你自己的正常水平,就值得复盘。
希望这篇文章对你有帮助。如果你在 Opus 5.5 上的限额并不比在 Opus 5 上更宽松,请通过 /feedback 告诉我们。
延伸阅读:有效管理成本 · 模型配置 · 在 Claude Code 中选择 Claude 模型和投入程度 · 投入程度 · 提示词缓存 · 最大化你的 Claude Code 会话价值
感谢 Michael Segner、Kacie Jenkins 和 Molly Vorwerck 的审阅。
You don't set out to buy millions of tokens. You set out to build a feature, finish a migration, or run a task. The token count is whatever the model needed to get there.
Two models with the same cost per token can cost very different amounts on the same task. One reads the code once. The other reads it, tries a fix, and reads it again. Each of those steps is a turn, and each turn resends the conversation so far. So the model that needs more turns costs more, even at the same price.
By the end of this post you should be able to answer three questions about your own work:
The tradeoff I want to share upfront is that every way to spend fewer tokens can also cost you a finished task. Lower effort, a smaller model, or less context can all certainly save tokens. A retry costs more than those savings. This post attempts to put a price on each tradeoff.
Some numbers here are list prices, and some are illustrations built from them. The figures are interactive, so change the inputs as you read. These are best effort illustrations, so be sure to check our docs and your own math.
A task in Claude Code is a loop. The model reads the conversation, calls a tool, reads the result, and goes round again until it's done. Each trip round the loop is one request. Four things set what the loop costs.
Turns. Every turn resends the conversation so far. Fewer turns means less input processed.
Cache reads. Most of what a turn resends is text the model saw on the previous turn. It's billed as a cache read, at a small fraction of the input price.
Output token type. The most expensive tokens, at five times the input price. Thinking is billed as output, so a model that reasons less on the way to the answer costs less.
Model. Each model has its own prices, listed on the pricing page, so the model you pick sets the price of every token.
Our examples use Opus 5.5 API list prices: $4 per million input tokens, $20 per million output tokens and $0.20 per million cache reads. Like the calculator further down, the examples bill cached input at the read price and everything else at the input price, and leave out cache writes. The token counts are illustrations.
Let’s say a task starts with 20K tokens of context and grows to 120K as the model reads files and tool results. At 40 turns, the average turn sends about 70K tokens. That's about 2.8M input tokens for the task, though the conversation never grew past 120K. With 90% read from cache, the input costs about $1.62. The same task in 25 turns processes about 1.75M tokens and costs about $1.02 in input.
A turn costs more than the tokens it adds, because it resends everything before it. So the cheapest turn is the one you don't need.
One habit that can cut turns is giving the model a way to check its work. For example, a test to run, a build, or a script that calls the endpoint. A model that can check its own work finds its mistakes earlier.
A model that gathers what it needs in one pass, and batches its tool calls, pays the resend fewer times too.
The same 2.8M input tokens cost $11.20 if none come from cache. At a 90% hit rate they cost $1.62, and at 96% about $0.99. No other setting moves input cost this much. A steady session keeps a high hit rate on its own. I cover some actions to avoid breaking your cache later in this post.
On Opus 5.5, an output token costs 100 times a cache read. The 60K output tokens of a typical task cost $1.20, the same as reading 6M tokens from cache. Output includes thinking. You pay for all of it, even when Claude Code only shows you a summary. That's why effort, which mostly changes how much the model thinks, moves the bill so much.
A model with cheaper cache reads mostly helps long sessions. One with cheaper output mostly helps tasks that need a lot of reasoning.
Two things changed: the price, and how much work the model does.
Every price line is lower. Input and output tokens are 20% cheaper than on Opus 5. Cache reads are 60% cheaper. The input price falls, and the read rate falls with it, from a tenth of the input price to a twentieth. Fig A compares the two models per million tokens. These are API list prices. On a Pro, Max or Team plan, the lower Opus 5.5 price is passed on to your limits, including cached context, so they go about 25% further than on Opus 5. The extra cut on cache reads is an API price change.
On an API key, the cache-read price cut matters most for Claude Code. A long agentic session spends most of its input on cache reads. In the session priced in Fig B below, the cache line falls from $1.00 to $0.40, the largest drop on the receipt.
How much you save depends on the shape of your work. A session that is mostly cache reads can save up to 60% on input. A short question with no cache and a long answer can save up to 20%, because output dominates it. Most Claude Code tasks sit between the two. The calculator below shows where yours sits.
Opus 5.5 can use more tokens on an answer, because it always thinks before it replies. We expect people to get more done on Opus 5.5, but it varies by task, so measure it on your own work. Fig C compares cost per task on the two models. This part depends on your work far more than the price does.
On a well-scoped task, both models finish in about the same number of turns, and the price cut is all you get. The gap should be biggest on open-ended tasks, where a model can spend many turns on the wrong idea. No single number holds for every codebase, so measure it (see the last section).
Long runs end with a report. Opus 5.5 closes a long run with what it changed, what it found, and what it needs from you. That can save money too, because you rerun a session less often when you can see what happened.
Fig B prices one session on both models with the same token counts. So the difference is the price change and nothing else. Switch models to compare. The token counts are illustrative.
at Opus 5 list prices
Fig B.
Illustrative session with the same tokens on both models, so this is the price change alone.
Fig B. Illustrative session with the same tokens on both models, so this is the price change alone.
The receipt has the three lines /usage shows for a session. Cache reads are the biggest line by tokens, at 2M. Output is the smallest by tokens and the biggest by cost. Fresh input sits between them. It covers the first read of each file and each new tool result.
Fig B gives both models the same token counts, so it shows the price change alone. Your own sessions can use more or fewer tokens on Opus 5.5. Priced that way, the session costs about 31% less.
A recorded run adds the second effect, the change in how much work the model does. On a task with a false start, the gap should widen. Try your own numbers
Set what one of your tasks uses, or start from a preset. The presets are pretty illustrative but I’d still recommend doing your own math. Cached input bills at the cache-read price and fresh input at the input price, so the cache slider shows how much of the gap comes from cache reads.
To fill the sliders from a real session, run /usage at the end of a task. The Session block gives input, output and cache figures. The last slider is your assumption about how much less work Opus 5.5 does on your tasks. Leave it at 0% for the price change alone. To set it from your own work, here's how: run the same task on Opus 5 and on Opus 5.5, and compare turns and output tokens. Measure it yourself walks through it, and Reading a session shows what to check in /usage.
Everything sent to the model across all turns, cached or not.
Includes thinking, which is billed as output.
Leave at 0% for price alone. Opus 5.5 does more with fewer tokens, but measure that on your own tasks.
Opus 5 per task
Opus 5.5 per task
Change per task
A month is working days. List prices. No batch or volume discounts, and cache writes are not counted (see the caching section below).
Opus 5.5’s lower price makes each token cost less. How you run a session decides how many tokens you use, and these steps help.
Effort sets a general disposition for how many tokens the model spends on each turn: its thinking, the text it writes, and its tool calls. At lower effort it makes fewer tool calls and keeps them shorter. Opus 5.5 has four levels (low, medium, high and xhigh), plus max for a single session. Pick a level below to see when to use it and the command that sets it.
Levels run from least to most thinking per turn.
Claude Code sets a default level for each model, and /effort status shows yours. Try medium for well-scoped, day-to-day work. When medium stalls, try high. It spends more per turn than medium, but less than moving to a bigger model. Use low for mechanical work, like renames or applying a known pattern across files.
A rough way to think about effort pricing: say high adds 20K thinking tokens across a task. On Opus 5.5 that's $0.40. A retry loop of ten turns at 100K of cached context, with 10K output tokens in total, costs about the same. So high pays for itself on a task where it saves one retry. On a task medium would have finished the first time, it's wasted.
The clearest sign you need more effort is a fix that stops at one layer.
Say a field is renamed in an API handler. At medium, the model updates the handler, the handler's tests pass, and the client still sends the old field. It did what it was asked. It just didn't read far enough to find the second caller. At high, it spends more turns reading call sites before it writes, and it changes both layers in one pass.
A check can catch the same bug. If the model can run a test that goes through the client, the old field fails that test on the turn it was written, at medium. So before you raise effort, check whether the model has a way to check its work. A test run costs one turn and its output. More effort adds thinking to every turn.
If upgrading effort levels and adding checks doesn’t work, then switch to a bigger model.
In Claude Code, run /effort with a level, for example /effort high. /effort status prints the current level. You can change it mid-task, and the new level applies to the next request.
Changing effort or thinking settings clears the cached conversation, because those settings are part of the prompt the cache matches. The next request pays the cache-write price on the whole conversation.
Model choice sets the price of every token in a session, so it moves the bill more than effort does. It also reaches further. Every subagent that inherits the main model inherits its price too. Most days need three models: a small one for lookups, Opus 5.5 for work you supervise closely, and a bigger one for the hardest tasks.
Use Opus 5.5 for work you supervise: feature work across a few files, debugging, and code review with follow-up edits. You read what it does and step in when it drifts, so the loop stays short. Moving up to Fable 5.1
Move up to Fable 5.1 when the result matters more than the token price. For example long runs you won't supervise, problems with no existing pattern in the codebase, and large changes that coordinate many subagents. Don't wait for a third failure. If Opus 5.5 on high hits the same problem twice, switch, and switch back once it's solved. For interactive work, Opus 5.5 is a better fit as it has lower latency and costs less.
Fable 5.1 lists at $10 per million input tokens and $50 per million output, two and a half times the Opus 5.5 price. Its cache reads cost $0.25 per million, only 1.25 times the Opus 5.5 rate, because they bill at 0.025 times its input price. So the gap is smallest on a long, cache-heavy run, and largest on a task that writes a lot.
Switch at a natural break. The cache belongs to the previous model, so expect the first turn on the new model to pay the write price on the whole conversation. Run /compact first, or start a fresh session with a short written plan, to make that turn smaller. Run /model with an alias or a model name to switch. /model also saves your choice as the default for new sessions, so switch back when the hard part is done.
Move down to Sonnet or Haiku for lookups, not for writing code: subagents that search and summarize, reading logs and test output, and "where is this defined" questions. For a mechanical edit across many files, keep Opus 5.5 and set effort to low. The edit stays on the model that writes the rest of your code, at a lower cost per turn.
To put a subagent on a smaller model, set model: haiku or model: sonnet in its definition. To put every subagent on one model, set the CLAUDE_CODE_SUBAGENT_MODEL environment variable. A model named in a subagent's definition overrides the variable. A subagent with no model setting runs on your main model, unless the variable is set.
Each subagent runs in its own context window and hands back a summary, so its file reads stay out of your main conversation. It still pays for its own tokens, so the model setting decides what that spend costs.
The tradeoff: a small model that misreads a search result sends the main model after the wrong file, and the main model pays for the detour. Keep the small model on work where a mistake is cheap to spot, like finding files, running tests and reading logs.
Keep judgment calls on the main model. The opusplan alias splits the work a different way: Opus plans in plan mode, and Sonnet carries out the plan. That puts the code edits on Sonnet, the opposite of the advice above. Measure it on your own tasks before you make it a default.
Instructions written for an older model can make Opus 5.5 write more and repeat tool calls. Run /claude-api prompt-audit in Claude Code to check your Claude Code setup, such as your skills and CLAUDE.md file, for these prompting anti-patterns. It also checks the code of an app you build on the Claude Platform.
We tested this on a migration from Opus 4.8 to Opus 5.5, using an internal customer support benchmark of 44 tickets whose prompt had several of these patterns. The move to Opus 5.5, at low effort, cut the benchmark's cost by about 18%. Running prompt-audit cut it by a further 9%, to about 25% below the Opus 4.8 starting point. The audit removed ritual instructions that made the model write more and repeat tool calls: a mandatory six-step procedure, a scratchpad rule, a verify-twice rule, and instructions that contradicted each other.
That result comes from one benchmark, so treat it as an example rather than a number to expect. Run the audit, then compare /usage on a real task before and after (see Measure it yourself).
Claude Code handles caching and compaction for you. How you run a session decides how much they save.
Claude Code caches the parts of a request that repeat, such as the system prompt, tool definitions, and the conversation so far.
On Opus 5.5 a cached read costs 5% of a fresh input token. Writing to the cache costs more than a fresh read, at 1.25 times the input price for a five-minute cache and twice the input price for a one-hour cache, on today's pricing. Each hit resets the lifetime at no charge.
In Claude Code the lifetime depends on how you pay. On a Claude subscription it's an hour. On an API key or a cloud provider it's five minutes by default, and a subscription drops to five minutes once it's drawing on usage credits.
At 120K tokens of context, a five-minute write on Opus 5.5 costs about $0.60 and a read about $0.02. One write costs as much as 25 reads. On an API key, a six-minute coffee break turns the next $0.02 read into a $0.60 write. A one-hour write at the same size costs about $0.96, and on the API you can pay that premium to cover the gaps in your day.
The cache stores a prefix, so it can reuse only the part of a request that matches the previous one from the start.
A steady session appends to the end of the conversation on every turn and keeps its hit rate high. Anything that changes an earlier part of the request lowers it. Changing the tool definitions clears the whole cache, and a change to the system prompt clears it from that point on, which is almost everything.
In practice, expect a cache write when:
So set these up when the session starts, and leave them alone while it works.
Every turn resends the whole context, so a turn costs more as the context grows, even with a warm cache. At 20K tokens of context a turn's cache read costs about $0.004 on Opus 5.5. At 150K it costs about $0.03, and 30 turns at that size spend $0.90 on reads alone. The same 30 turns at 20K cost about $0.12. On Claude 4.6 and later models a bigger context window doesn't change the price per token, so the cost comes entirely from resending the conversation.
Much of that context is left over from earlier work: a stack trace from an hour ago, a file you've finished with, the output of a test run you've since fixed. It's all still sent on every turn.
When a session gets close to its context limit, Claude Code summarizes older history so later turns send less. Run /autocompact with a token count to change how full the context gets before that happens.
Two commands let you do this yourself. /clear empties the conversation and costs nothing, so use it when you move to unrelated work. /compact keeps continuity and costs one request. It reads the conversation it summarizes, and you can say what to keep, for example /compact keep the failing test names and the schema change.
A rough price for compacting at 150K tokens is about $0.25. That's the read, a summary of a few thousand output tokens, and a new cache write on the shorter context. Each later turn saves about $0.025 in reads, so the compaction pays for itself within about ten turns. A compaction just before you finish costs more than it saves.
The summary also loses detail. A compaction in the middle of a debugging session can drop the one log line that mattered. Compact at a natural break, and when the next step depends on something specific, say so in the /compact instruction.
Your CLAUDE.md file loads into the context at the start of every session, so each line in it is part of what every turn resends. The costs docs suggest keeping it under 200 lines. MCP tool definitions are deferred. Only tool names and server instructions load at the start, and a full definition loads when its tool is used. Run /mcp to see which servers are connected, and turn off the ones you aren't using.
The table lists the other billing rules that affect a Claude Code session, with a link to the docs where one exists.
The figures in this post are illustrations. Your codebase, prompts and habits are different, so measure cost on your own tasks. Here's how to check.
Check three things in /usage at the end of a task.
For a baseline, the Claude Code costs docs give an average across enterprise deployments of about $13 per developer per active day, and under $30 per active day for 90% of users. A session that costs well above your own normal level is worth reviewing.
I hope this post was helpful. If your limits don’t go further on Opus 5.5 than on Opus 5, tell us with /feedback.
Further reading: Manage costs effectively · Model configuration · Choosing a Claude model and effort level in Claude Code · Effort · Prompt caching · Maximizing the value of your Claude Code sessions
With thanks to Michael Segner, Kacie Jenkins and Molly Vorwerck for their reviews.
来源:Claude:Blog(网页)· claude.com
配图