AI News
Anthropic 发布三项测量指标,公开 AI 驱动 AI 研发的进度数据
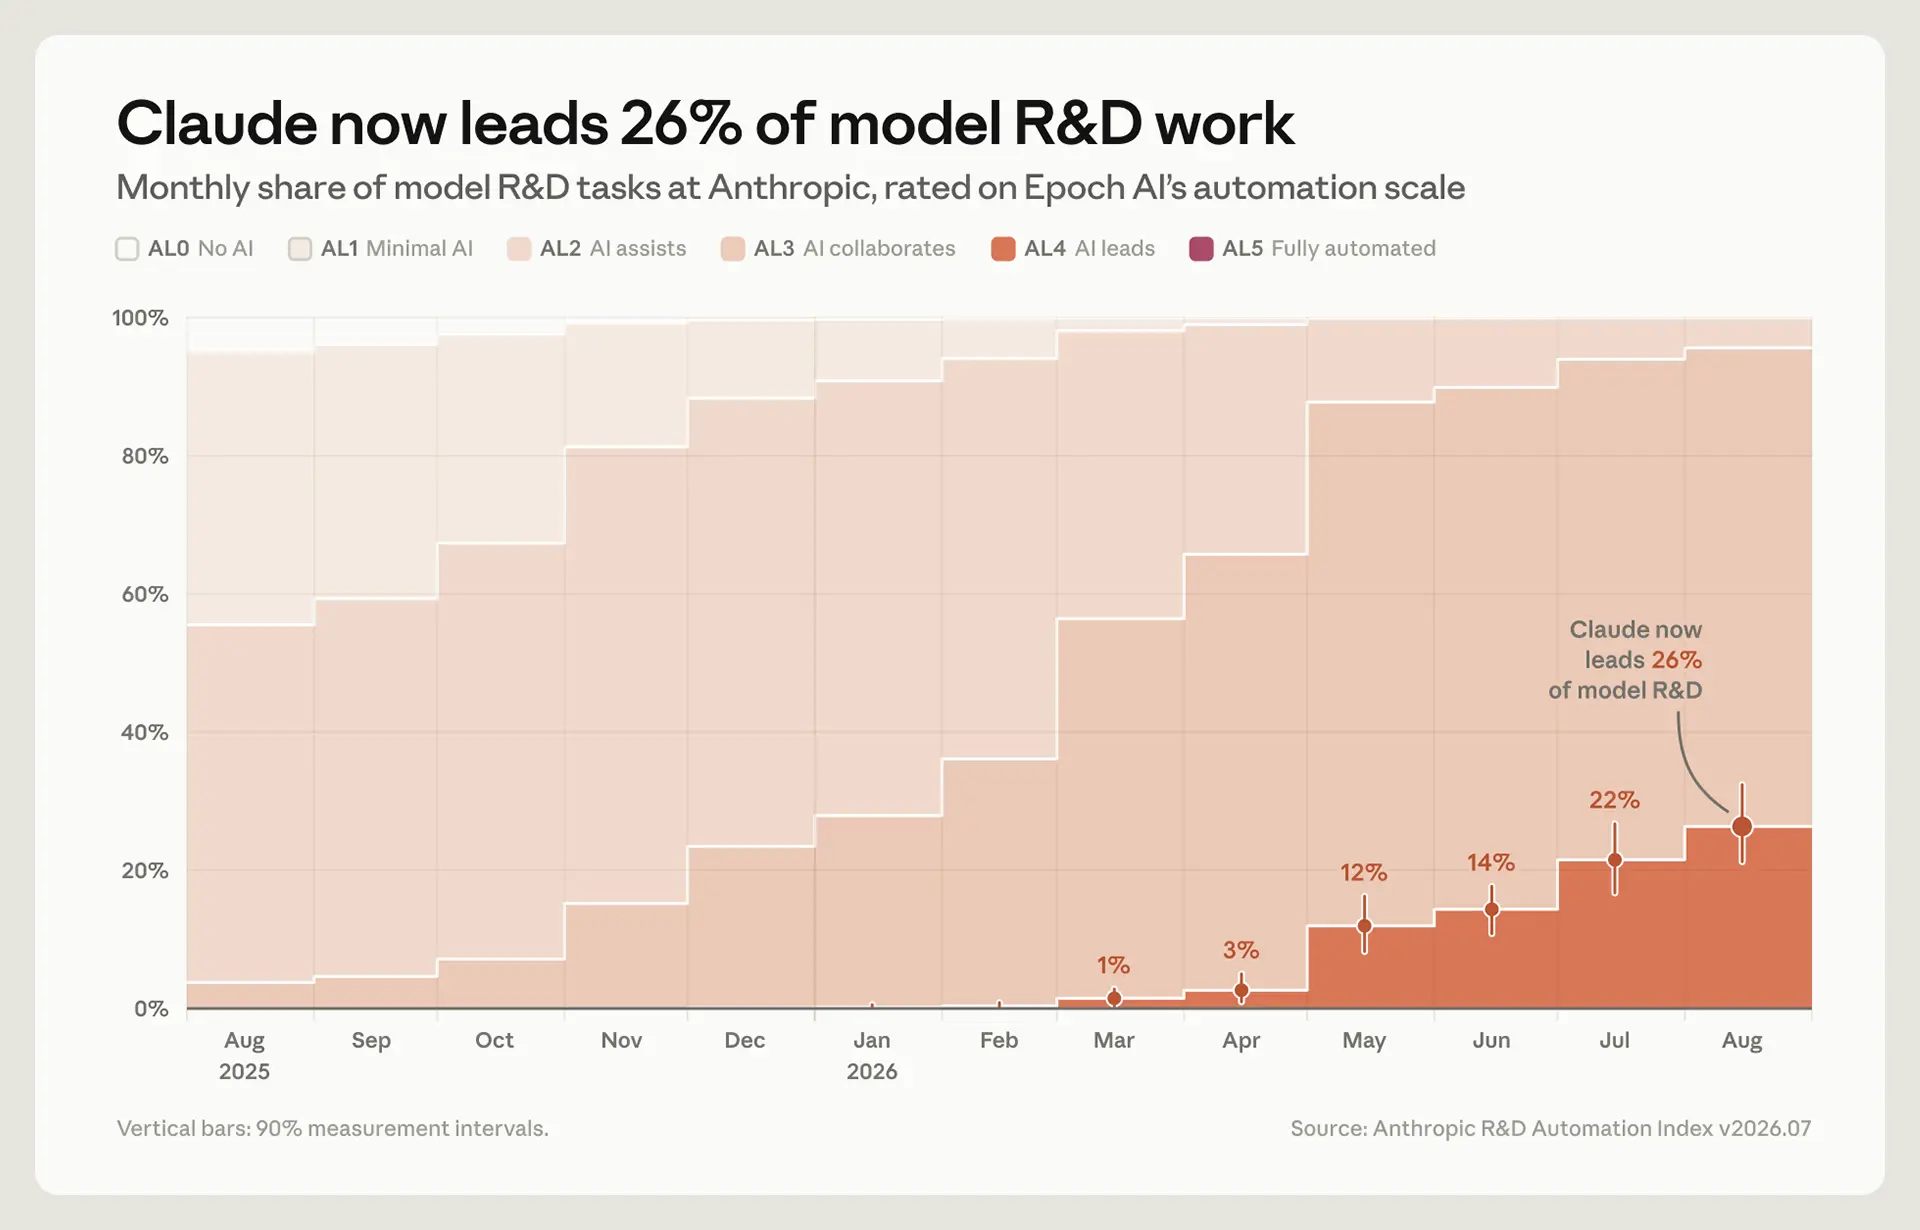
Anthropic 发布测量框架,公开三项内部指标以帮助外界了解前沿实验室的 AI 开发节奏。截至 2026 年 8 月,Claude 在 26% 的 Anthropic AI 研发工作中处于主导角色,90% 以上的工作至少达到协作级;内部平台约有 3 万个 Agent,10 亿多次决策中 0.002% 被在线监控拦截;7 月一周内约 6% 的 AI 研发算力用于安全工作。
AI 系统的能力正以指数级速度增强,并已开始将更多自身构建过程自动化。当全世界在考虑放缓前沿 AI 发展步伐之际,公众需要更多信息。
在这篇文章中,我们列出了一些测量工具,它们能够揭示 AI 发展的三个关键方面:
我们还提供了来自 Anthropic 内部的这些指标快照。需要重点指出的是,如果按照 Anthropic CEO Dario Amodei 的呼吁,在前沿发展节奏上实现协调,我们预计这些数字将会发生变化。我们计划在 Anthropic 内部嵌入来自多个组织的独立第三方评估人员,并让他们获得与内部风险评估团队相当的内部流程、系统和数据的访问权限。这些第三方将验证安全实践、报告事件,并监控诸如本文所列的关键指标。
我们报告这些测量结果,是因为它们能让公众、第三方和政府更好地了解前沿实验室内部 AI 发展的速度。对于每一项测量,我们都会说明我们测量了什么、测量结果显示了什么,以及要以他人可验证的形式定期发布这些测量结果需要具备哪些条件。我们在附录中分享了方法细节。
本文中的测量聚焦于模型是如何构建的。通过更好地理解模型的生产过程,我们更有可能将模型输入(如算力)与模型输出(如能力)关联起来。它们与能力评估形成互补,后者衡量的是模型能做什么。我们通过负责任扩展政策(RSP)风险报告单独发布这些内容,其中包括关于我们的模型在多大程度上加速 AI 研发的证据。在我们关于先进 AI 的政策提案先进 AI 框架(AAIF)中,我们提出了任何实验室发布安全模型都应遵循的道路规则,包括政府可以要求的透明度义务,例如风险报告。这些拟议的测量方法和政策共同构成了从实验室外部监测 AI 发展速度的起点。
为什么要衡量 AI 主导的研发? 前沿 AI 实验室越来越多地使用 AI 来构建未来的 AI 模型。这一过程让民主国家的实验室能够更快地开发出能力更强的模型,并在模型发布前对其进行更多的安全性和测试工作,从而在保持前沿的同时确保 AI 的益处。然而,模型加速自身开发可能会让人更难理解或控制这些系统。因此,分享这些指标非常重要,以便了解世界距离实现递归式自我改进(即模型完全自主地构建其继任者)还有多远。
我们衡量了什么。 我们构建了一个原型指数,用来衡量 Anthropic 的 AI 研究与开发(R&D)中有多少是由 Claude 完成的,称之为 Anthropic R&D 自动化指数。它的构建方式是:对公司内部进行的每一种 AI R&D 工作进行编目,评估每项任务当前的自动化程度,并对这些评分进行汇总。
我们发现了什么。 为了衡量 AI 在 Anthropic 进行 AI R&D 的程度,我们使用了由 Epoch AI 开发的自动化评级量表,它衡量的是“自动化水平”,即 AL。该量表从 AL0(无 AI 参与)到 AL5(AI 完全自主运行,无需人类介入)。在 AL3 中,AI“协作”:它可以在人类的密切指导下完成大量工作。在 AL4 中,AI“主导”:它可以在仅给出高层提示词的情况下端到端完成大部分任务,而由人类进行监督1。
截至 2026 年 8 月,
任何 AI 开发者今天都可以报告的内容。任何前沿开发者都可以使用公开的方法论定期发布这些指标。这将使这些数字能够随时间推移进行比较,并有可能在不同实验室之间进行比较。
在这类报告上实现跨实验室比较面临两个障碍。第一是缺乏共同的方法论。第二,我们正在使用自己的模型来评估自己的系统,这可能意味着“评判”模型可能会犯下与被检查模型相同类型的错误。为应对这些挑战,开发者的测量结果可以由第三方或其他开发者的模型进行验证,同时设置护栏以限制竞争敏感数据的交换。这些措施还可以成为更严格要求的触发条件,例如在新模型被用于进一步 AI 研发之前设定固定的测试窗口。
为什么要衡量对智能体的监督? 与其他前沿开发者一样,Anthropic 的员工越来越多地将任务委派给能够长时间半自主工作、并且会相互委派工作的智能体。随着工作日益自动化,从“AI 协作”走向“AI 主导”,智能体可能会做出更具重大影响的决策,例如接下来该 pursue 哪条研究方向。
这些决策既需要防护措施来阻止单个智能体的有害行为,也需要一套监督机制来发现可能只在众多智能体之间才会出现的问题。在我们迄今为止的监控数据中,单个智能体很少出现不当行为。但当经济中有数百万乃至数十亿个智能体在运行时,即便是罕见事件也可能经常发生。
我们衡量了什么。 我们构建了一套系统,使我们能够监督并干预 AI 智能体在 Anthropic 系统上所采取的行动。在此,我们考察三个不同的指标:覆盖率,它描述的是智能体的行动在执行前或执行后经过监控的比例;审查 延迟,即从行动发生到其被审查之间的时间,先由自动监控器审查,再由人工审查;以及升级率,即被阻止/重定向(对于在线监控器而言)或被标记以供进一步审查(对于离线监控器而言)的智能体活动所占的比例。
我们的发现。 截至 2026 年 8 月,在我们最常用的内部平台上,Anthropic 随时都有大约 30,000 个智能体在从事研究和工程工作。这些测量仅覆盖该平台。这些智能体的行为受到两类监控器的约束,概述如下:
AI 开发者今天可以报告什么。任何在自身研究与工程工作负载上运行智能体的开发者,都可以发布同样的指标:覆盖率(被监控的智能体活动占比)、审查延迟(被标记的活动多久得到审查),以及升级率(监控系统拦截或标记的智能体活动占比)。这些指标合在一起,将让社会得以看清监督是否跟上了 AI 在 AI 研发中日益增长的作用。我们在近期的风险报告中发布了所有这些测量结果。
开发者应当分享已知的智能体不当行为被监控系统捕获的频率,并应当让第三方独立进行这类测试。过去,METR 曾对我们的离线监控平台进行独立红队测试。如上所述,我们目前正在 Anthropic 设立外部第三方评估方。
为什么要衡量算力分配?广义而言,AI 开发者将算力用于构建更强大的模型、服务客户,以及安全导向的工作,例如审计模型的“思维”、训练模型生物以研究失准,以及评估模型能否安全部署。理解 AI 开发者如何分配其算力,可以让你看出开发者将资源聚焦于何处,以及这种聚焦如何随时间变化。
此外,算力是 AI 研发过程中最可验证的投入之一,这意味着它可能成为未来节奏调控努力中的关键杠杆。一项协调一致的节奏调控努力可以鼓励企业增加全行业分配给安全的算力,并将更多资源投入到对齐、可解释性、安全测试和评估中。
我们测量了什么。 我们考察了 Anthropic 在 7 月 13 日至 7 月 20 日期间如何使用其全部算力的一个快照2。为此,我们将每一项工作负载归入少量类别,然后考察用于 AI 研发的算力中有多少流向了安全工作。
安全研究按其性质而言,通常比前沿训练运行消耗更少算力,因此算力并不能完美代表一家公司对安全的重视程度。这是因为安全研究由个别研究人员设计实验构成,尽管运行实验并不特别消耗算力,但设计实验本身颇为耗时。因此,这一指标的价值不在于绝对数字,而更多在于它提供了一种直观的机制,可以在不同开发者之间以及不同时间之间进行同类比较。
我们发现了什么。 在所考察的这一周内,用于 AI 研发的算力中约有 6% 分配给了安全,而用于 AI 驱动的 AI 研发的算力中约有 12% 分配给了安全。
这些是刻意保守的估计。例如,如果某个 token 用于推进能力的程度与用于推进安全的程度相当,它就不会被计入这些指标。此外,这些指标没有计入安全防护分类器,那是一笔单独的、规模相当的计算量,它让我们的模型对世界更加安全。
AI 开发者今天就可以报告的内容。任何前沿开发者都可以公布其 AI 研发算力中用于安全工作的比例,同时公布类别定义,并由独立第三方核查分类。
安全研究很难与能力研究区分开来,每个开发者都会倾向于宽松地划定界限。举证责任应当落在开发者身上,由其证明某项工作与安全相关。开发者、政府和更广泛的研究界都将受益于事先就统一定义达成共识。这样的衡量方式可以为未来的行动提供参考,例如实验室就用于安全研究的算力占比作出承诺,或对用于 AI 研究智能体的算力占比设定上限。
当世界考虑为前沿发展设定节奏时,我们应当尽一切可能缩小前沿实验室所知与公众所知之间的差距。这意味着更好地衡量 AI 的发展、公开报告相关情况,并让社会有机会决定如何使用这些信息。我们希望通过发布这些衡量数据来树立这种透明度的典范,我们也将继续这样做。
以下是我们已制作原型的所有测量指标的方法论细节。
我们是如何做到的。 自动化指数需要三样东西:一份 Anthropic 内部所有 AI 研发任务的完整图谱、一套评定自动化水平的方法,以及一套为任务加权的方法,从而让重要领域的工作比不那么重要的工作占更大权重。没有人能凭一己之力列出一家前沿 AI 公司所有 AI 研发任务,至少达不到我们想要的细粒度。于是我们以自下而上的方式,从 Slack 及各类内部文档等工作记录中构建出这份任务清单。
在 2026 年 7 月的每一周,我们从构成模型研发闭环的每个部门中随机抽取 20% 的员工。一个 Claude 研究智能体利用 Slack 和内部文档审阅每位被抽中员工当周的工作,并列出他们所从事的任务。对 2026 年 7 月的每一周重复这一流程,我们就得到了一份约 15,000 项细粒度模型研发任务的平铺清单。
随后我们用 Claude 将这些任务组织成一棵层级树,根节点为全部模型研发,向下分支出训练和产品等领域,再分为预训练和强化学习,如此逐层细分到越来越具体的工作类型。最终得到的树在不同深度上共有 542 个节点,其中 378 个是叶子节点,例如“评估平台缺陷诊断与修复”“RL 沙箱出口与网络策略”以及“服务事故复盘”。
我们冻结这棵树,使我们所做的每一次测量都针对同一套工作集合进行。
对于树中的每个节点(一个描述其下所有工作的任务类别),一个 Claude 智能体会深入研究这类工作在整个公司是如何完成的:由谁来做、使用什么工具,以及其中有多大比例由 AI 完成。随后,一个独立的 Claude 评判者会阅读所得的证据,并给出六个自动化等级中的一个,采用 Epoch AI 提出的量表来区分 AI 被使用的程度:无 AI 参与、极少量 AI 参与、AI 辅助、AI 协作、AI 主导或 AI 自主。当我们对某个月的自动化程度进行评级时,我们只允许执行评级的研究智能体查看该月或更早的证据。
为了将所有自动化等级评级汇总为一个数字,我们希望为树中的每个节点赋予一个权重,对应这项工作对整个模型研发工作的重要程度。我们没有自行决定哪些类型的工作比其他工作更重要,而是用投入到该任务的人时数量作为代理指标。利用我们的样本,我们让 Claude 研究每个人在 2026 年 7 月每一周都在做什么工作。
每个人每周获得一个单位的权重,平均分配到他们那一周所从事的各项任务上。如果 A 从事了四项任务,每项获得 0.25;如果 B 从事了十项,每项获得 0.10。一个类别的权重是分配给它的所有人时权重之和。这是一种粗略的近似,但平均而言这套方案表现得合理:它会给被更多人分配到的类别赋予更大的权重。
这捕捉到了什么,又遗漏了什么。 首先,自动化评级取决于评判模型。为了核验这些评级,我们请负责相关工作领域的 Anthropic 员工对其所在领域的相对自动化程度进行评分。为确保读数不带偏见,员工在评分时并不知道模型收集了哪些证据,也不知道模型是如何评判这些证据的。我们的评判模型与人类的一致程度,大致相当于人类彼此之间的一致程度(模型与人类完全一致的比例为 59%,人类与人类之间为 35%),且模型与人类的评级在 97% 的情况下相差不超过一个等级。在边界情形上仍存在真实的意见分歧空间,例如“AI 协作”究竟在哪里结束、“AI 主导”又从哪里开始。
其次,这个任务篮子是被冻结的。以 2026 年 7 月为基线、不断增长的指数数值告诉我们,人类在当时所做的工作正在被自动化;但它本身并不能告诉我们,是否正在出现人类转移过去的新型工作。为了探究这一点,我们基于 2026 年 1 月的数据构建了这棵冻结任务树的另一个版本,并将 2026 年 2 月至 7 月每月新增的任务与 2026 年 1 月的任务篮子进行对比。我们发现,在 1 月和 7 月这两个任务篮子之间,“新颖”任务的数量并未上升,这表明在我们这一分析粒度上,模型研发工作的结构是稳定的。尽管如此,我们计划定期重建任务篮子,并酌情对已发布的自动化数值进行版本更新。
我们是如何做的。 在我们最常用的内部智能体脚手架中,有两项设计选择让我们能够更容易地发现未知的未知,并让智能体相互监督:
这捕捉到了什么,又遗漏了什么。在如此规模的智能体活动下,很难确定我们是否已完整掌握所有可能出现的行为类型,也很难确定我们是否让这些模式对人类监督而言足够清晰可读。我们从事这类监测只有数月,而非数年,并且预计智能体监测这门科学在未来会发生相当大的变化。
我们是如何做的。我们从现有的算力监测工具入手;Anthropic 想必和每一家前沿开发者一样,拥有若干为容量规划而构建的监测工具,它们会定期采样加速器使用情况,并根据其元数据为工作负载打上尽力而为的标签(即研究与模型开发、内部使用、第一方推理等等)。第三方云算力上的使用情况由供应商向我们报告并纳入其中。这项工作中大部分的工作量,就是把上述这些现有来源拼接在一起。
随后我们使用 Claude,通过一个提示词分类器将每个工作负载归类为安全工作或 AI R&D。安全工作的定义是:其主要目的是让 AI 系统更安全、更可理解或更安全可靠的工作。其他一切,包括能力研究、训练生产模型、产品开发和开发者工具,都被计为 AI R&D。对能力的帮助与对安全的帮助相当的工作,也被计为 AI R&D,因此安全所占的份额是偏保守的。
针对研究训练和评估运行,我们构建了一个分类器,它会读取运行的元数据及其使用的代码,并返回一个分类结果、一份理由说明和一个置信度。我们没有对当周近 10,000 次运行全部进行分类,而是抽取了其中约 14%,并在抽样时向使用算力最多的运行倾斜,以便结果反映算力实际流向了哪里,而不是有多少次运行。
对于 AI 研究智能体的推理,同一分类器的一个变体会读取智能体的会话记录。当会话记录无法获取时(通常是因为相关工作被隔离),我们按用户所属团队对其进行分类,或保守地默认将其归类为 AI 研发。我们计划改进这条流水线,使独立的第三方能够对随机抽取的任务和会话记录子样本重新运行该分类器,并核查分类结果和总量。
You’re helping to perform an internal audit at the frontier AI company Anthropic to track where our research compute goes. The aim of the audit is to produce a public-facing breakdown of the usage of all of our AI accelerator chips into a handful of buckets. One split we particularly care about is the division between compute which was spent on safety research versus other R&D. Your job is to look at one research job at a time, figure out what it was doing, and assign it to one of those two buckets. [...] Safety and/or security research is work whose dominant purpose is making AI systems safer, more understandable, or more secure. This work can be broken down into a few main categories: [...] On the other hand, the following work falls outside of the scope of safety research: [...] Here are some boundary cases, along with how to think about them: [...] 这捕捉到了什么,又没有捕捉到什么。 这项工作的主要经验是,对什么算安全工作和什么不算安全工作进行分类虽然困难,但可以处理,因为这些类别之间的界限并非黑白分明。例如,关于可扩展监督的研究可能让未来的模型更加对齐,同时让当前的模型在商业上更有用——很难确定这主要是在推进安全还是推进能力。我们发现,为每项任务给出详尽的书面定义,并附上清晰的边界案例(上方为节选),能让分类器与人工评审者的判断达成一致,人工与机器评分者之间的差异在一到两个百分点以内。但有些案例即便经过数小时的人工审查也难以判定。我们的定义只是众多合理选择中的一种;不同的开发者,或者监管机构,可能会划出不同的界线。
还有三项局限值得注意。第一,我们所依赖的许多底层标签(即运行原因、工作负载标签、API 流量来源)是由自动化规则设定的,偶尔也由用户直接设定,属于尽力而为,并未经过验证。在大多数情况下,我们预期分类是准确的,但在某些情况下,使用情况可能被错误标注,而我们的流水线未必能捕捉到。
一项旨在让外部人士信任的测量,必须是完整、准确且在技术上强制执行的。第二,该测量只覆盖了一周,这足以证明测量本身可以做到,但不足以显示出有意义的趋势。第三,也是最重要的一点,算力占比只衡量了花费了多少。一个更高效的安全分类器,或为生产模型配备更快的推理栈,会降低安全部分的占比,但这并不意味着我们在安全方面做的工作变少了。
我们自己的分类器开销随着效率提升而下降,而当生产推理比分类器更高效时,这一开销又上升了。
本文由 Marina Favaro 和 Phillie Wright 共同撰写,Santi Ruiz、Adam Farina 和 Sarah Pollack 提供了编辑支持。Jack Clark 提供了研究方向。Dan Altman、Kerry Persen、AJ Kourabi、James Bradbury、Holden Karnofsky、Kevin Troy 和 Avital Balwit 提供了反馈。技术概念验证由 Jun Shern Chan、Brian Calvert、Francesco Mosconi、Henry de Valence、Fabien Roger 和 Joe Benton 开发。Shan Carter、Johnnie Gomez、Maria Gonzalez、Fayaz Ashraf、Monika Tuchowska 和 Kim Withee 制作了可视化内容。Alex Cloud 和 Andrea Vallone 组织了一场研讨会,与外部专家一起对这些及其他测量提案进行了红队测试。
感谢 Nate Rush、Eli Lifland 和 Peter Wildeford,他们也提供了反馈。
AI systems are becoming exponentially more powerful and have begun to automate more of the process of building themselves. As the world considers slowing the pace of frontier AI development, the public needs more information.
In this post, we lay out measurement tools that can illuminate three critical aspects of AI development:
We also provide a snapshot of these metrics from inside Anthropic. It’s important to note that we would expect these numbers to shift if there were coordination on pacing the frontier, as called for by Anthropic CEO Dario Amodei. We plan to embed independent third-party evaluators from multiple organizations at Anthropic, and give them access to internal processes, systems, and data comparable to what internal risk assessment teams have. These third parties will verify safety practices, report incidents, and monitor key metrics such as the ones in this piece.
We are reporting these measurements because they give the public, third parties, and governments better visibility into the pace of AI development inside frontier labs. For each measurement, we describe what we measured, what the measurement showed, and what it would take to publish these measurements regularly in a form others can verify. We share methodological details in the Appendix.
The measurements in this piece are focused on how models are built. By better understanding the production process of models, we have a better chance of correlating model inputs, like compute, with model outputs, like capabilities. They complement capability evaluations, which measure what models can do. We publish those separately through our Responsible Scaling Policy (RSP) risk reports, which include evidence on how much our models are accelerating AI R&D. In our policy proposal on advanced AI, the Advanced AI Framework (AAIF), we propose rules of the road for how any lab releases safe models, including transparency obligations that governments could require, such as risk reports. Together, these proposed measurements and policies are a starting point for monitoring the pace of AI development from outside the labs.
Why measure AI-led R&D? Frontier AI labs increasingly use AI to build future AI models. This process allows labs in democratic countries to develop more capable models more quickly and conduct more safety and testing on models before they are released to secure AI’s benefits while staying on the frontier. However, models accelerating their own development could make it more challenging for humans to understand or control these systems. It is therefore important to share these metrics to understand how close the world is to reaching recursive self improvement (a model fully autonomously building its successor).
What we measured. We built a prototype index of how much of Anthropic’s AI research and development (R&D) is performed by Claude, called the Anthropic R&D Automation Index. It’s built by cataloguing every kind of AI R&D work done at the company, rating how automated each task currently is, and aggregating those ratings.
What we found. To measure the extent to which AI is doing AI R&D at Anthropic, we use an automation rating scale developed by Epoch AI that measures “Automation Level,” or AL. It runs from AL0 (no AI involvement) to AL5 (AI operates fully autonomously, with no human in the loop). In AL3, AI “collaborates”: it can do large chunks of work under close human direction. In AL4, AI “leads”: it can complete most of the task end-to-end from a high-level prompt, while the human supervises1.
As of August 2026,
What any AI developer could report today. Any frontier developer could publish these measures regularly, using a public methodology. This would enable the numbers to be compared over time, and potentially across labs.
Two obstacles stand in the way of cross-lab comparison on this type of reporting. First is the lack of a common methodology. Second, we’re using our own models to evaluate our systems, which could mean that the “judge” model could make the same kinds of errors as the model it is checking. To address these challenges, a developer’s measurements could be verified by a third party, or by other developers’ models, with guardrails in place to limit the exchange of competitively sensitive data. These measures could also become the trigger for stronger requirements, like a fixed testing window before a new model is used for further AI R&D.
Why measure oversight of agents? Like other frontier developers, Anthropic employees increasingly delegate tasks to agents that work semi-autonomously for long stretches, and that delegate work to one another. As work becomes increasingly automated, from “AI collaborates” toward “AI leads,” agents could make more consequential decisions, such as which research direction to pursue next.
These decisions need safeguards to block harmful behavior from an individual agent, as well as an oversight regime to detect problems that might only arise across many agents. In our monitoring data to date, individual agents rarely misbehave. But when there are millions or billions of agents operating in the economy, even rare events can happen regularly.
What we measured. We’ve built a system that lets us oversee and intervene in actions AI agents take on Anthropic’s systems. Here, we consider three different metrics: coverage, which describes the share of an agent’s actions that pass through a monitor before or after execution; review latency, which is the time between an action and its review, first by an automated monitor and then by a human; and escalation rate, whichis the share of agent activities that are either blocked/redirected (in the case of online monitors) or flagged for further review (in the case of offline monitors).
What we found. As of August 2026, there were approximately 30,000 agents doing research and engineering work at Anthropic at any one time in our most-used internal platform. These measurements cover this platform only. The actions of these agents are constrained by two kinds of monitors, summarized below:
What an AI developer could report today. Any developer running agents on its own research and engineering workloads could publish the same measures: coverage (the share of agent activity that is monitored), review latency (how soon flagged activities are reviewed), and escalation rate (what share of agent activities the monitors block or flag). Together, these measures would allow society to see whether oversight is keeping pace with the growing role of AI in AI R&D. We published all of these measurements in our recent risk report.
Developers should share how often known agent misbehavior is caught by monitors, and should have third parties do this kind of testing independently. In the past, METR has independently red-teamed our offline monitoring platform. As described above, we are now setting up external third party evaluators at Anthropic.
Why measure compute allocation? Broadly speaking, AI developers use compute for building more powerful models, serving customers, and safety-focused work like auditing a model’s “thoughts”, training model organisms to study misalignment, and evaluating whether a model can be safely deployed. Understanding how AI developers allocate their compute can tell you where a developer is focusing its resources and how that focus changes over time.
Additionally, compute is among the most verifiable inputs to the AI R&D process, meaning that it could be a critical lever in a future pacing effort. A coordinated pacing effort could encourage companies to increase the compute allocated to safety across the industry and devote more resources to alignment, interpretability, safety testing, and evaluation.
What we measured. We examined a snapshot of how Anthropic used all of its compute from July 13 to July 202. To do that, we sorted every workload into a small number of categories, then asked how much of the compute going to AI R&D was safety work.
Safety research tends to use less compute than frontier training runs by its nature, so compute is an imperfect proxy for how much a company focuses on safety. This is because safety research consists of individual researchers designing experiments, which is time-consuming even though running the experiments is not particularly compute-intensive. The value of this metric, therefore, is less the absolute numbers and more that it provides a straightforward mechanism to compare like with like, across developers and over time.
What we found. Over the examined week, about 6% of compute that went to AI R&D was allocated toward safety, and about 12% of compute that went to AI-driven AI R&D was allocated toward safety.
These are deliberately conservative estimates. For example, if a token was used to advance capabilities as much as it was to advance safety, it was not counted in these metrics. Additionally, these metrics do not account for safeguards classifiers, which are a separate, comparable amount of compute that make our models much safer for the world.
What an AI developer could report today. Any frontier developer could publish what share of its AI R&D compute goes to safety work, with the category definitions published alongside and the classification checked by an independent third party.
Safety research is hard to distinguish from capabilities research, and each developer will be tempted to draw the line generously. The burden of proof should sit with the developer to show that work is safety-related. Developers, governments, and the wider research community would benefit from converging on a shared definition ahead of time. A measurement like this could inform future actions, such as a lab’s commitments about the share of compute going to safety research, or limits on the share of compute going towards AI research agents.
As the world considers pacing the frontier, we should do everything possible to minimize the gap between what frontier labs know and what the public knows. This means better measuring the development of AI, reporting on it publicly, and giving society an opportunity to decide how to use this information. We hope to model that transparency by releasing these measurements, and we’ll continue to do so.
Here are methodological details on all of the measurements we’ve prototyped.
How we did it. The Automation Index requires three things: a complete map of all the AI R&D tasks being done at Anthropic, a way to rate the level of automation, and a way to weight the tasks, so that important areas of work count for more than less important ones. No one person can list every AI R&D task at a frontier AI company by hand, at least not at the granularity we want. Instead we constructed this list of tasks in a bottom-up manner from work records including Slack and various sources of internal documentation.
For each week in July 2026, we randomly sampled 20% of staff from each department that make up the model R&D loop. A Claude research agent reviewed each sampled person’s week using Slack and internal documentation, and listed the tasks they worked on. Repeating this for each week in July 2026 gives us a flat list of ~15,000 granular model R&D tasks. We then used Claude to organize these tasks into a hierarchical tree, starting from all model R&D at the root and branching into areas such as training and product, then pretraining and reinforcement learning, and so on down to increasingly specific kinds of work. The resulting tree has 542 nodes at different depths, of which 378 are leaves like “eval platform defect diagnosis and fixes,” “RL sandbox egress and network policy,” and “serving incident postmortems.” We freeze this tree so that every measurement we make happens against the same basket of work.
For each node in the tree (a task category describing all the work beneath it), a Claude agent deeply researches how that kind of work is done across the company: who does it, with what tools, and how much of it AI performs. An independent Claude judge then read the resulting evidence and assigned one of six automation levels, adopting a scale proposed by Epoch AI to differentiate the degree to which AI is used: no AI involvement, minimal AI involvement, AI assists, collaborates, leads, or is autonomous. When we rate a given month’s automation, we only allow the research agents that do the ratings to see evidence from that month or earlier.
To aggregate all the automation level ratings into one number, we want to give each node in the tree a weight corresponding to how important that work is to the overall model R&D effort. Rather than deciding ourselves what kinds of work are more important than others, we used the amount of person-time dedicated to that task as a proxy. Using our sample, we had Claude research what each person worked on during each week of July 2026. Each person gets one unit of weight per week, split evenly across the tasks they worked on that week. If person A worked on four tasks, each gets 0.25; if person B worked on ten, each gets 0.10. A category’s weight is the sum of all the person-time weights given to it. This is a crude approximation, but on average the scheme behaves sensibly: it assigns more weight to categories that many people are assigned to.
What this does and doesn’t capture. First, the automation ratings depend on the judge model. To check them, we asked Anthropic staff who own the relevant work areas to rate the relative automation of their areas. To ensure an unbiased read, staff made their ratings without knowing what evidence the models had gathered or how they had judged that evidence. Our judge model agreed with humans about as often as humans agreed with each other (model-versus-human exact agreement was 59%, human-versus-human was 35%), and model and human ratings were within one level of each other 97% of the time. There remains real room for disagreement on borderline cases, such as where exactly “AI collaborates” ends and “AI leads” begins.
Second, the basket is frozen. A growing index number on a July 2026 baseline tells us that the work humans were doing at that time is being automated; it does not, on its own, tell us whether new kinds of work are appearing that humans have shifted onto. To investigate this, we constructed an alternate version of the frozen tree from January 2026 data, and compared new tasks arriving every month from February to July 2026 against that January 2026 basket. We found no rise in the number of “novel” tasks between the January and July baskets of tasks, suggesting that the structure of model R&D work is stable at our level of analysis. Nevertheless, we plan to rebuild the basket of tasks periodically and re-version our published automation numbers as appropriate.
How we did it. In our most commonly used internal agent scaffold, two design choices allow us to more easily detect unknown unknowns and let agents monitor each other:
What this does and doesn’t capture. At this scale of agent activity, it is hard to be certain we have a complete picture of all possible kinds of behaviors, or that we are making these patterns adequately legible to human oversight. We have been doing this kind of monitoring for months, not years, and expect the science of agent monitoring to change considerably going forward.
How we did it. We started with our existing compute monitoring tools; Anthropic, like presumably every frontier developer, has several monitoring tools built for capacity planning that periodically sample accelerator usage and tag workloads with best-efforts labels (i.e., research and model development, internal usage, first-party inference, and so on) based on its metadata. Usage on third-party cloud compute is reported to us by the providers and folded in. Most of the work of this exercise was stitching these existing sources together.
We then used Claude to classify each workload as either safety work or AI R&D via a prompted classifier. Safety work was defined as work whose dominant purpose is making AI systems safer, more understandable, or more secure. Everything else, including capability research, training production models, product development, and developer tooling, was counted as AI R&D. Work that helps capability as much as it helps safety was also counted as AI R&D, so the safety share is conservative.
For research training and evaluation runs, we built a classifier that reads the run’s metadata and the code it used, and returns a classification, a justification, and a confidence level. Rather than classify all of the week’s almost 10,000 runs, we sampled about 14% of them, weighting the sample toward the runs that used the most compute, so that the result reflects where the compute actually went, rather than how many runs there were. For inference for AI research agents, a variant of the same classifier read the agent’s session transcript. Where transcripts were inaccessible (usually due to the work being compartmentalized), we classified them by the user’s team or conservatively defaulted to classifying them as AI R&D. We plan to refine this pipeline so that an independent third-party could re-run the classifier on a random subsample of jobs and transcripts and check both the sorting and the totals.
You’re helping to perform an internal audit at the frontier AI company Anthropic to track where our research compute goes. The aim of the audit is to produce a public-facing breakdown of the usage of all of our AI accelerator chips into a handful of buckets. One split we particularly care about is the division between compute which was spent on safety research versus other R&D. Your job is to look at one research job at a time, figure out what it was doing, and assign it to one of those two buckets. [...] Safety and/or security research is work whose dominant purpose is making AI systems safer, more understandable, or more secure. This work can be broken down into a few main categories: [...] On the other hand, the following work falls outside of the scope of safety research: [...] Here are some boundary cases, along with how to think about them: [...] What this does and doesn’t capture. The main lesson of this exercise is that classifying what is and isn’t safety work is difficult but tractable, since the boundary between these categories is not black and white. For example, research on scalable oversight might make future models more aligned and current models more commercially useful — it’s difficult to determine whether this is primarily safety- or capabilities-advancing. We found that an extensive written definition of each task, with clear boundary cases (an excerpt is above), gets the classifier to agree with human reviewers within one or two percentage points of difference between the human and machine raters. But some cases were too difficult to determine even after several hours of human review. Our definition is one reasonable choice among many; a different developer, or a regulator, might draw the line differently.
Three further limitations matter. First, many of the underlying labels we relied on (i.e., reasons for runs, workload tags, the source of API traffic) are set by automated rules, or occasionally directly by users, and are best-effort, not verified. In most cases, we expect that our classifications are accurate, but in some cases usage may be mislabeled and our pipeline would not necessarily catch it. A measurement meant to be trusted by outsiders will need to be complete, accurate, and technically enforced. Second, the measurement covers one week, which is enough to show that the measurement can be made, but not enough to show a meaningful trend. Third, and most importantly, compute share measures only what is spent. A more efficient safety classifier, or a faster inference stack for production models, lowers the safety portion, but doesn’t mean we’re doing less safety work. Our own classifier overheads have fallen with efficiency improvements, and have risen when production inference was more efficient than the classifiers were.
Marina Favaro and Phillie Wright co-authored this piece, with editorial support from Santi Ruiz, Adam Farina, and Sarah Pollack. Jack Clark provided research direction. Dan Altman, Kerry Persen, AJ Kourabi, James Bradbury, Holden Karnofsky, Kevin Troy, and Avital Balwit provided feedback. Technical proofs of concepts were developed by Jun Shern Chan, Brian Calvert, Francesco Mosconi, Henry de Valence, Fabien Roger, and Joe Benton. Shan Carter, Johnnie Gomez, Maria Gonzalez, Fayaz Ashraf, and Monika Tuchowska, and Kim Withee created the visuals. Alex Cloud and Andrea Vallone organized a workshop to red team these and other measurement proposals with external experts.
Thanks to Nate Rush, Eli Lifland, and Peter Wildeford, who also provided feedback.
来源:Anthropic:Newsroom(网页)· anthropic.com
配图